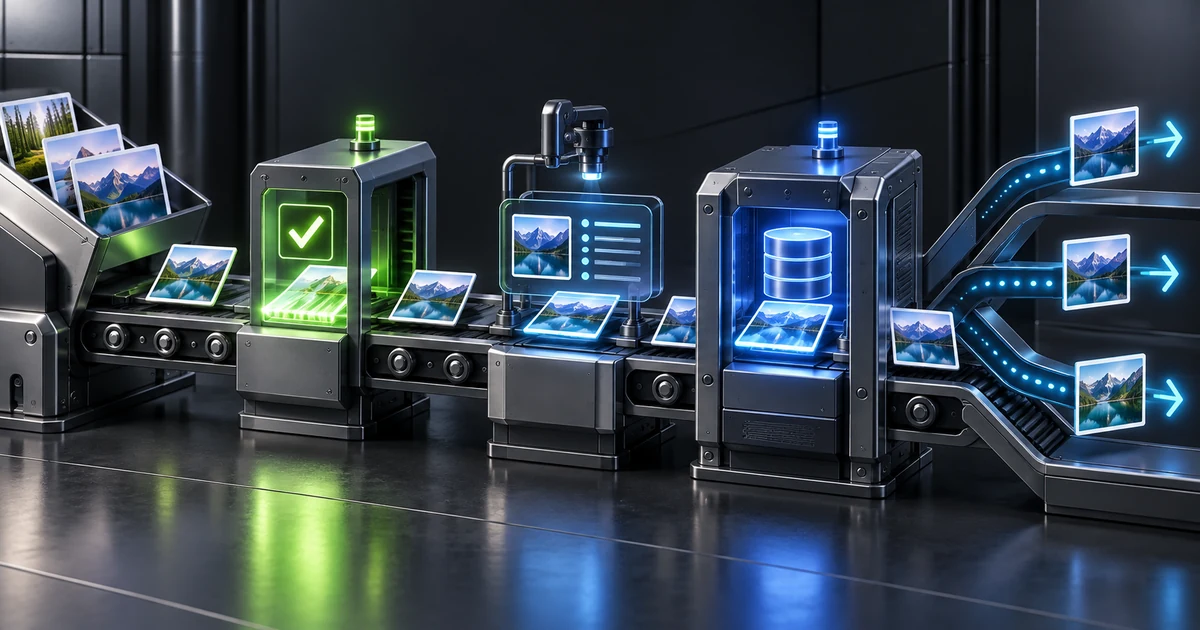
Short answer: Accept uploads through a controlled endpoint or signed direct-upload flow, validate the real file, assign a stable asset ID, store the original, extract trusted metadata, and move the asset through explicit processing states. Make every retry idempotent.
An upload endpoint is not finished when it returns a URL. It creates a source asset that future transformations, cache keys, editorial records, and deletion workflows depend on. A fragile ingestion model spreads that fragility across the entire delivery system.
Direct upload or application proxy?
In an application-proxy flow, the browser sends bytes to your server, which validates and forwards them. This gives the application tight control but consumes its bandwidth, memory, and request time. Large uploads can compete with normal API traffic.
In a direct flow, the application issues a short-lived signed authorization and the client uploads to the media service or object store. This reduces application data transfer, but the server must still own policy and record completion. Do not give the browser a long-lived administrative credential.
Cloudinary documents authenticated and unsigned methods in its upload guide. If unsigned presets are used, restrict them carefully because they represent a public capability. Provider-specific controls should map to your application’s policy, not replace it.
What should be validated?
Validate file size, detected media type, dimensions, pixel count, frame count, and allowed encoding. Do not rely only on the filename extension or client-provided Content-Type. Decode with maintained libraries in a resource-limited environment and fail closed on malformed content.
Apply separate limits for animated images and high-resolution sources. A modest compressed file can expand into an enormous pixel buffer. Set time, memory, and dimension ceilings before expensive processing.
Treat metadata as untrusted input. Strip metadata that is unnecessary for delivery, especially location data, while preserving fields your workflow deliberately needs. Normalize orientation before downstream crop logic if that is part of the platform contract.
OWASP’s File Upload Cheat Sheet provides a broad security checklist. Adapt it to image-specific decoding and transformation risks.
Which identity should the asset receive?
Use a stable opaque asset identifier that does not depend on a mutable filename. Store the original filename as metadata if editors need it. Include a source version or content hash in delivery identity so replacing bytes does not silently reuse old derivatives.
Deduplication can be helpful but should be explicit. Two users uploading identical bytes may not imply shared ownership or lifecycle. A content hash can detect repeats while business records remain separate.
The upload response should return your canonical asset model, not a raw provider payload. Include asset ID, version, width, height, format, status, and safe preview information. The typed URL builder can consume that stable model.
Which states make failure recoverable?
Use explicit states such as initiated, uploading, received, validating, ready, rejected, and failed. Persist the state before asynchronous work starts. Each worker should be able to retry without creating another logical asset or overwriting a newer version.
Assign an idempotency key to the upload intent. If a client retries after a lost response, return the existing result. For multipart upload, track parts and finalization separately. Expire abandoned intents and incomplete uploads through a scheduled cleanup policy.
Do not publish a delivery URL until the source is validated and the required metadata exists. A placeholder status response is safer than letting the first public request discover a corrupt original.
Should derivatives be generated during upload?
Generate only predictable, high-value derivatives eagerly. A primary thumbnail, moderation preview, or guaranteed hero size may justify precomputation. Generating the full cross-product of widths, crops, qualities, and formats wastes work for variants never requested.
On-demand generation is effective when the allowed set is bounded and cold latency is acceptable. The first-request behavior described in the cold path guide should inform which critical derivatives you warm.
What should operations monitor?
Track upload attempts, accepted bytes, rejection reasons, validation duration, processing duration, ready rate, orphaned intents, retry count, and storage growth. Correlate application upload IDs with provider request IDs without exposing secrets.
Alert on a sustained rise in decode failures, timeouts, or assets stuck in a transitional state. A queue depth graph alone is not enough; age of the oldest item usually signals user impact more clearly.
Provide administrators a safe retry and quarantine workflow. Preserve enough diagnostic metadata to understand failure, but do not retain malicious or rejected files indefinitely without a policy.
A reliable upload pipeline creates a trustworthy asset before delivery begins. Stable identity, strict validation, explicit state, and idempotent recovery are what make later transformations and migrations routine instead of risky.
Leave a Reply